GeistBench
Observed results for configured AI agents in synthetic enterprise workspaces. Each release states which capabilities were evaluated, the limits of the evidence and whether comparisons are supported.
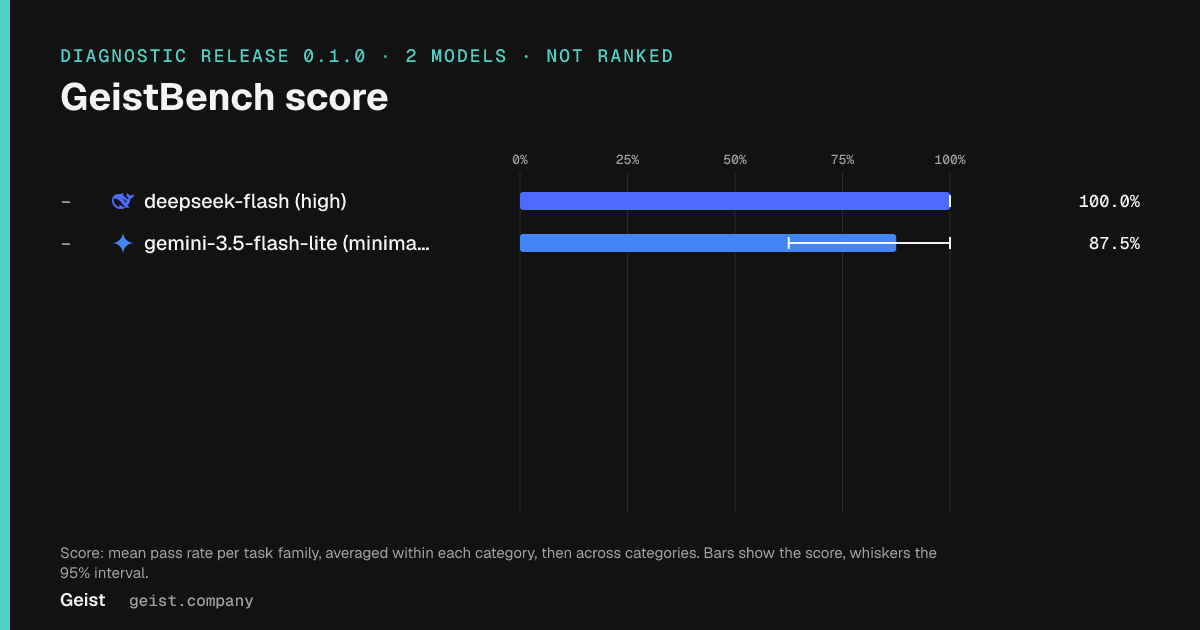
Score: mean pass rate per task family, averaged within each category, then across categories. Bars show the score, whiskers the 95% interval. How the score works
What this release evaluates
Business categories group tasks. They do not establish which product capabilities were tested. Coverage below refers only to this release's published evidence.
Categories included in this release: Tool reliability.
| Capability | Published evidence | What the evidence supports |
|---|---|---|
| Tool argument adherence | Published diagnostic only | Coached checks with supplied arguments. These do not establish end-to-end workflow ability. |
| World Map writes | Not reported | Capability-specific coverage is unavailable. Neither evaluation nor absence of evaluation can be inferred. |
| End-to-end World Map editing | Not evaluated in this release | This capability is outside the release's evaluated scope. |
| Video tool workflows | Not evaluated in this release | This capability is outside the release's evaluated scope. |
| Video understanding quality | Not evaluated in this release | This capability is outside the release's evaluated scope. |
Planned or implemented checks describe evaluation readiness. Executed means a run has retained evidence; validated means that evidence passed its review gates; published means approved results appear in a release. None of these states is inferred here from a category name or the presence of code.
- Models
- 2
- Configurations
- 2
- Categories
- 1
- Runs per task
- 3
GeistBench score
This release did not pass the claim gates for a comparison. Scores are shown in a fixed order, without ranks.
Show as table
| Configuration | Rank | Score | 95% interval | Status |
|---|---|---|---|---|
| deepseek-flash (high)DeepSeek · reasoning high · direct · in-app tools · direct writes · 16,384 max output tokens | – | 100.0% | 100.0% to 100.0% | Diagnostic release, no ranks |
| gemini-3.5-flash-lite (minimal)Google · reasoning minimal · direct · in-app tools · direct writes · 16,384 max output tokens | – | 87.5% | 62.5% to 100.0% | Diagnostic release, no ranks |
Share
https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/leaderboard-en.png<a href="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic#gb-overview"><img src="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/leaderboard-en.png" alt="GeistBench score, GeistBench release 0.1.0" width="1200" height="630"></a>Cost per task attempt
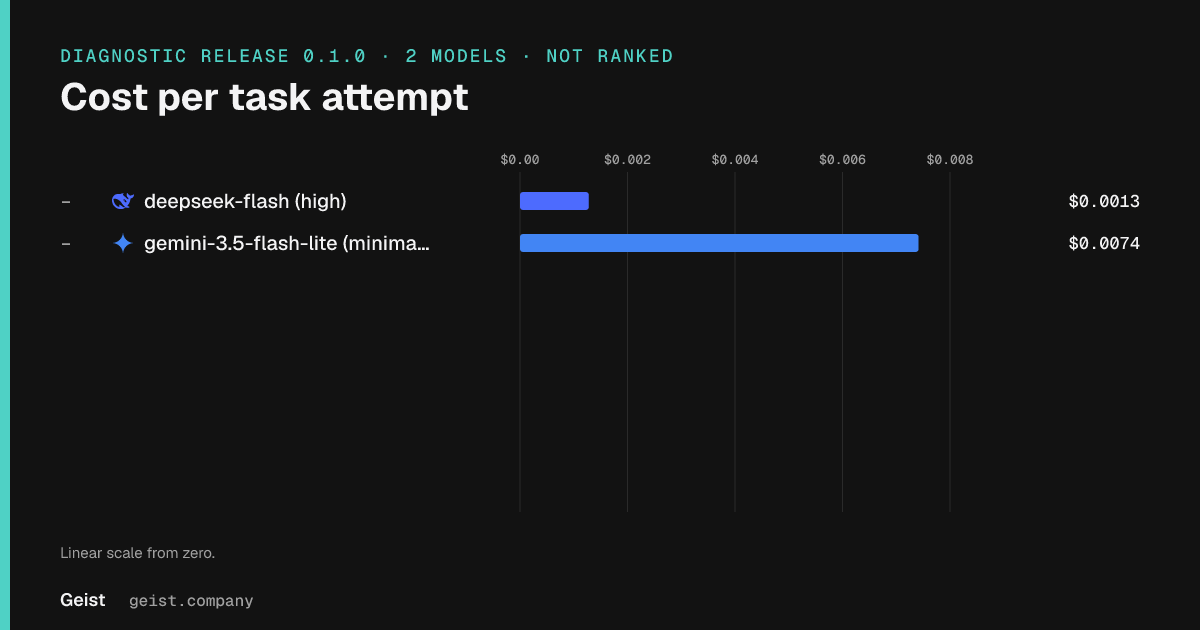
Recorded cost divided by the trials that have a cost, in USD. The table states the cost basis for each configuration. Lower is cheaper.
Show as table
| Configuration | Cost per attempt | Cost basis | Median wall time |
|---|---|---|---|
| deepseek-flash (high)DeepSeek · reasoning high · direct · in-app tools · direct writes · 16,384 max output tokens | $0.0013 | Catalog price estimate | Unavailable |
| gemini-3.5-flash-lite (minimal)Google · reasoning minimal · direct · in-app tools · direct writes · 16,384 max output tokens | $0.0074 | Catalog price estimate | Unavailable |
Share
https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/cost-en.png<a href="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic#gb-cost"><img src="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/cost-en.png" alt="Cost per task attempt, GeistBench release 0.1.0" width="1200" height="630"></a>Score vs cost
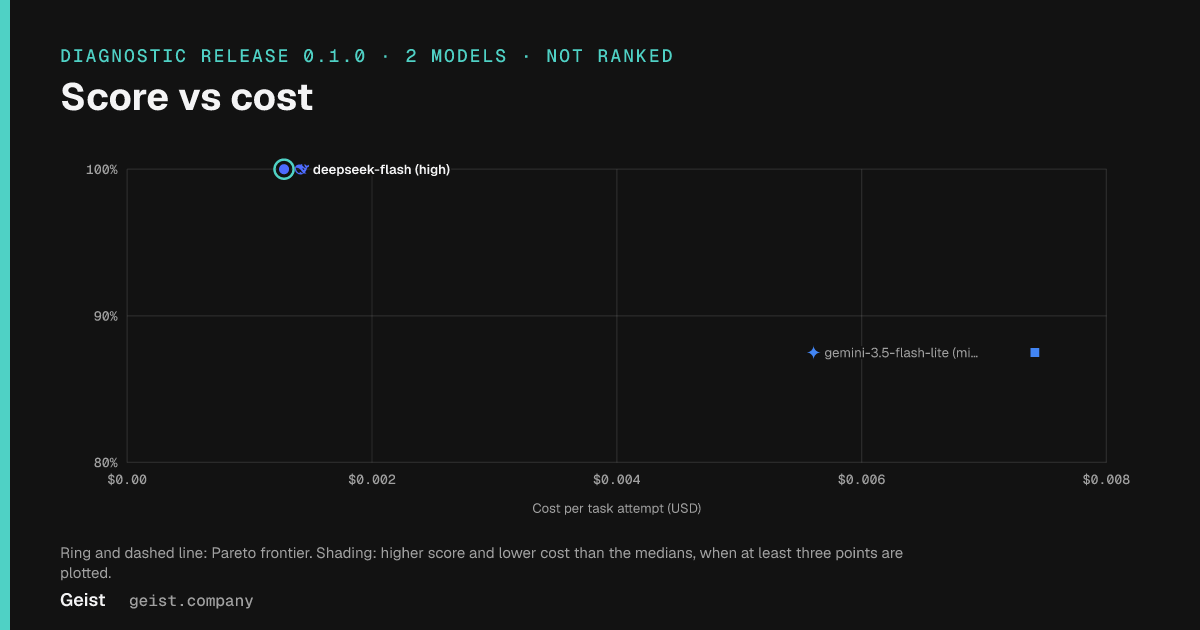
Each point is one configuration. On the Pareto frontier, no other plotted configuration costs no more and scores at least as high, with a strict improvement on either measure. Comparative releases plot ranked configurations only.
Show as table
| Configuration | Score | Cost per attempt | On frontier |
|---|---|---|---|
| deepseek-flash (high)DeepSeek · reasoning high · direct · in-app tools · direct writes · 16,384 max output tokens | 100.0% | $0.0013 | Yes |
| gemini-3.5-flash-lite (minimal)Google · reasoning minimal · direct · in-app tools · direct writes · 16,384 max output tokens | 87.5% | $0.0074 | No |
Share
https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/quadrant-en.png<a href="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic#gb-value"><img src="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/quadrant-en.png" alt="Score vs cost, GeistBench release 0.1.0" width="1200" height="630"></a>Where each configuration is strong
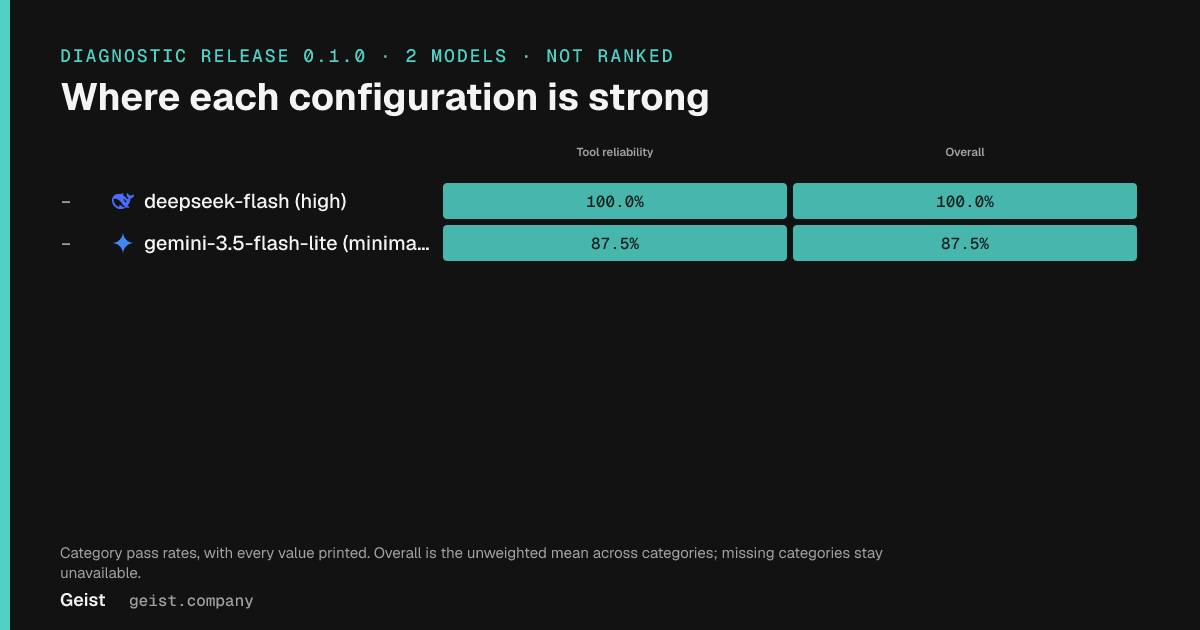
Category score per configuration. Stronger teal marks a higher score; every cell prints its value. Missing categories stay empty and are never filled in.
Share
https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/categories-en.png<a href="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic#gb-categories"><img src="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/categories-en.png" alt="Where each configuration is strong, GeistBench release 0.1.0" width="1200" height="630"></a>Peak is not the floor
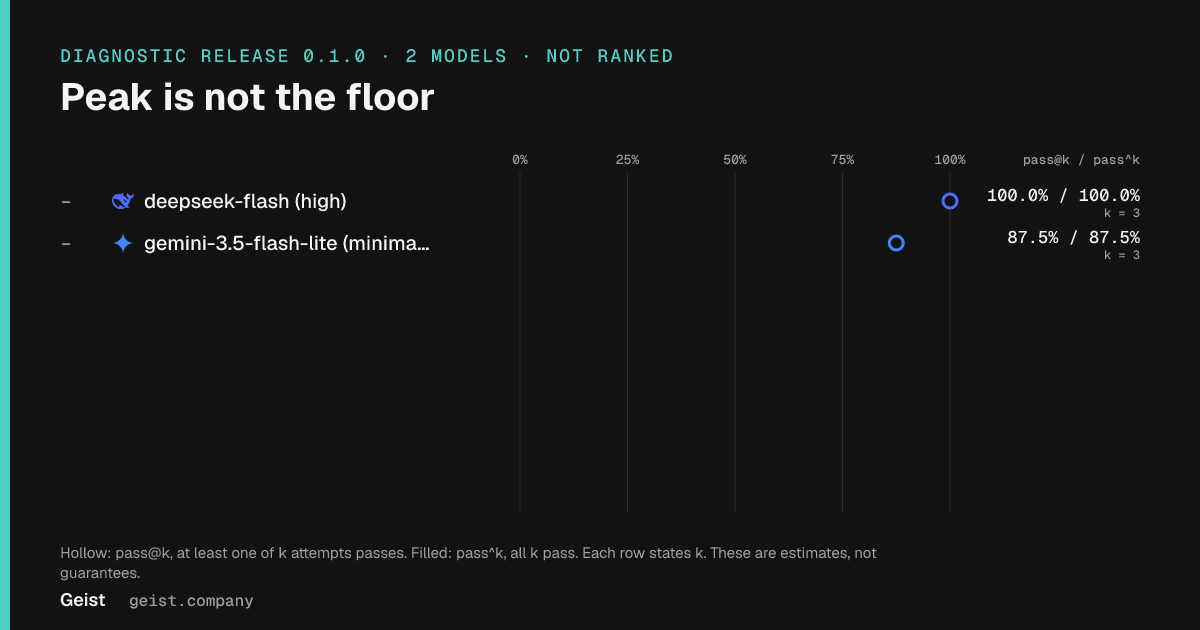
For each configuration's published k, pass@k estimates the chance that at least one of k attempts passes; pass^k estimates the chance that all k pass. Neither is a guarantee for a production attempt. The table lists k for each configuration.
Show as table
| Configuration | k | pass@k | pass^k |
|---|---|---|---|
| deepseek-flash (high)DeepSeek · reasoning high · direct · in-app tools · direct writes · 16,384 max output tokens | 3 | 100.0% | 100.0% |
| gemini-3.5-flash-lite (minimal)Google · reasoning minimal · direct · in-app tools · direct writes · 16,384 max output tokens | 3 | 87.5% | 87.5% |
Share
https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/reliability-en.png<a href="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic#gb-reliability"><img src="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/reliability-en.png" alt="Peak is not the floor, GeistBench release 0.1.0" width="1200" height="630"></a>German and noisy prompts
Deltas use only task families with both variants: German minus English, and noisy minus clean, in percentage points. Missing paired observations stay unavailable.
German vs English
Noisy vs clean
Show as table
| Configuration | German vs English | Noisy vs clean |
|---|---|---|
| deepseek-flash (high)DeepSeek · reasoning high · direct · in-app tools · direct writes · 16,384 max output tokens | Unavailable | Unavailable |
| gemini-3.5-flash-lite (minimal)Google · reasoning minimal · direct · in-app tools · direct writes · 16,384 max output tokens | Unavailable | Unavailable |
Share
https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/robustness-en.png<a href="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic#gb-robustness"><img src="https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic/charts/robustness-en.png" alt="German and noisy prompts, GeistBench release 0.1.0" width="1200" height="630"></a>How a number gets on this page
Release history and citation
Every published release keeps its own permanent page and JSON file. Releases are never pooled.
| Version | Published | Claim | Links |
|---|---|---|---|
| 0.1.0LatestShown | 8 October 2026 | Diagnostic | OpenJSON |
Cite this release
BibTeX
@misc{geistbench-0-1-0,
  title = {GeistBench release 0.1.0: observed results},
  author = {{Geist}},
  year = {2026},
  url = {https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic},
  note = {Summary hash bcd88ab15069cf9adc01846328722f7af64e6bff8741f4b6b39b93e64aad08a9}
}Plain text
Geist (2026). GeistBench release 0.1.0: observed results. https://geist.company/geistbench/releases/geistbench-b12-contract-20261008-diagnostic. Summary hash bcd88ab15069cf9adc01846328722f7af64e6bff8741f4b6b39b93e64aad08a9.
- Summary hash
bcd88ab15069cf9a
For AI labs and vendors
Request a benchmark run
- We run every configuration ourselves, under the published methodology and on the same tasks as every other configuration in the campaign.
- Results publish only in a release that passes the release gates, whatever they show.
- No pay-to-rank: a request cannot buy a rank, a placement or an exception to the gates.